GPT vs Claude vs Gemini vs Llama: The 2026 Comparison
· 9 min read
Vyom Solution
Founder & Lead Designer
Vyom Solution is a web studio based in India, designing and building custom websites for founders worldwide.
Long-form companion
Want the full story, examples, and context? Read GPT vs Claude vs Gemini vs Llama: AI Models Compared (2026) on the blog.
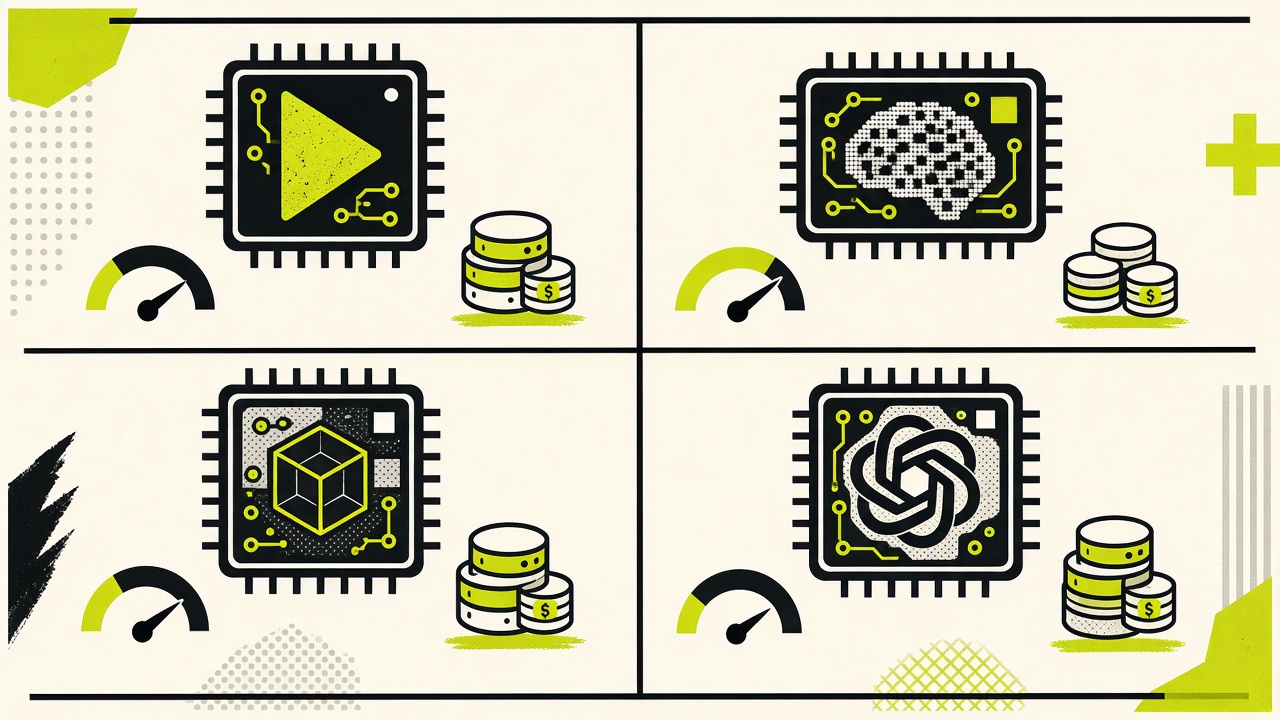
Model marketing changes weekly; your architecture should not. Use this matrix to match **latency**, **cost**, **context**, and **tool reliability** to the job — not hype.
Numbers are directional for mid-2026 tiers; always verify pricing on provider pages before budgeting.
▪2026 comparison matrix
Rate each family 1–5 for your workload. Pick the highest total for batch work; pick the highest speed + tools score for user-facing agents.
| Family | Speed | Cost efficiency | Long context | Tool use | Best fit |
|---|---|---|---|---|---|
| GPT-4o / o-series | 4 | 3 | 4 | 5 | General agents, complex tool chains |
| Claude Sonnet / Opus | 4 | 3 | 5 | 5 | Long docs, careful writing, code review |
| Gemini Flash / Pro | 5 | 5 | 4 | 4 | High volume, multimodal, Google stack |
| Llama 3.x (self-host) | 3 | 5* | 4 | 3 | Data residency, predictable unit cost |
▪Decision flow
Start with data: must payloads stay in your VPC? → self-host Llama or enterprise contract. Need sub-second chat on a budget? → Gemini Flash-class. Need reliable function calling? → GPT or Claude mid-tier and above.
For prose-heavy customer emails, Claude and GPT tend to need fewer retries; for classification at scale, lighter models win.
- ✓User-facing chat → prioritize latency and guardrails
- ✓Back-office batch → prioritize cost and context
- ✓Regulated data → prioritize hosting control over benchmark scores
▪Context windows — what actually matters
Large windows help when you must paste entire policy PDFs. Most SMB workflows fit under 32k tokens if you retrieve snippets instead of dumping whole drives.
Invest in retrieval and chunking before paying for maximum context every call.
▪Action Steps
- 1
List your top three AI tasks and score each column in the matrix.
- 2
Prototype the highest-stakes task on two providers for one week.
- 3
Lock one primary and one fallback model; document swap procedure.
- 4
Deep dive: blog model comparison.
▪Frequently Asked Questions
Is open source always cheaper?+
Unit economics can be — but include GPU, MLOps, and engineer time. Many teams start hosted, then self-host only hot paths.
Should I use one model for everything?+
Rarely. Route simple classification to a small model; reserve large models for customer-facing or multi-step agents.
How often should we re-evaluate?+
Quarterly for pricing; immediately when you add a new tool-calling step to production.